

UI-Venus
Collection
18 items • Updated • 41
Learning to Look Beyond Screens: Transferable Visual Observation from GUI Grounding
LBS-27B is an agentic vision-language model based on Qwen3.8-27b. It learns to select and inspect image regions through GUI grounding, then transfers this observation policy to general-domain visual question answering and high-resolution perception.
Training uses only synthetic GUI grounding data, with no general-domain data or VQA questions: approximately 10K cold-start SFT examples, followed by 80 GRPO steps with a batch size of 64 and 8 rollouts per prompt.
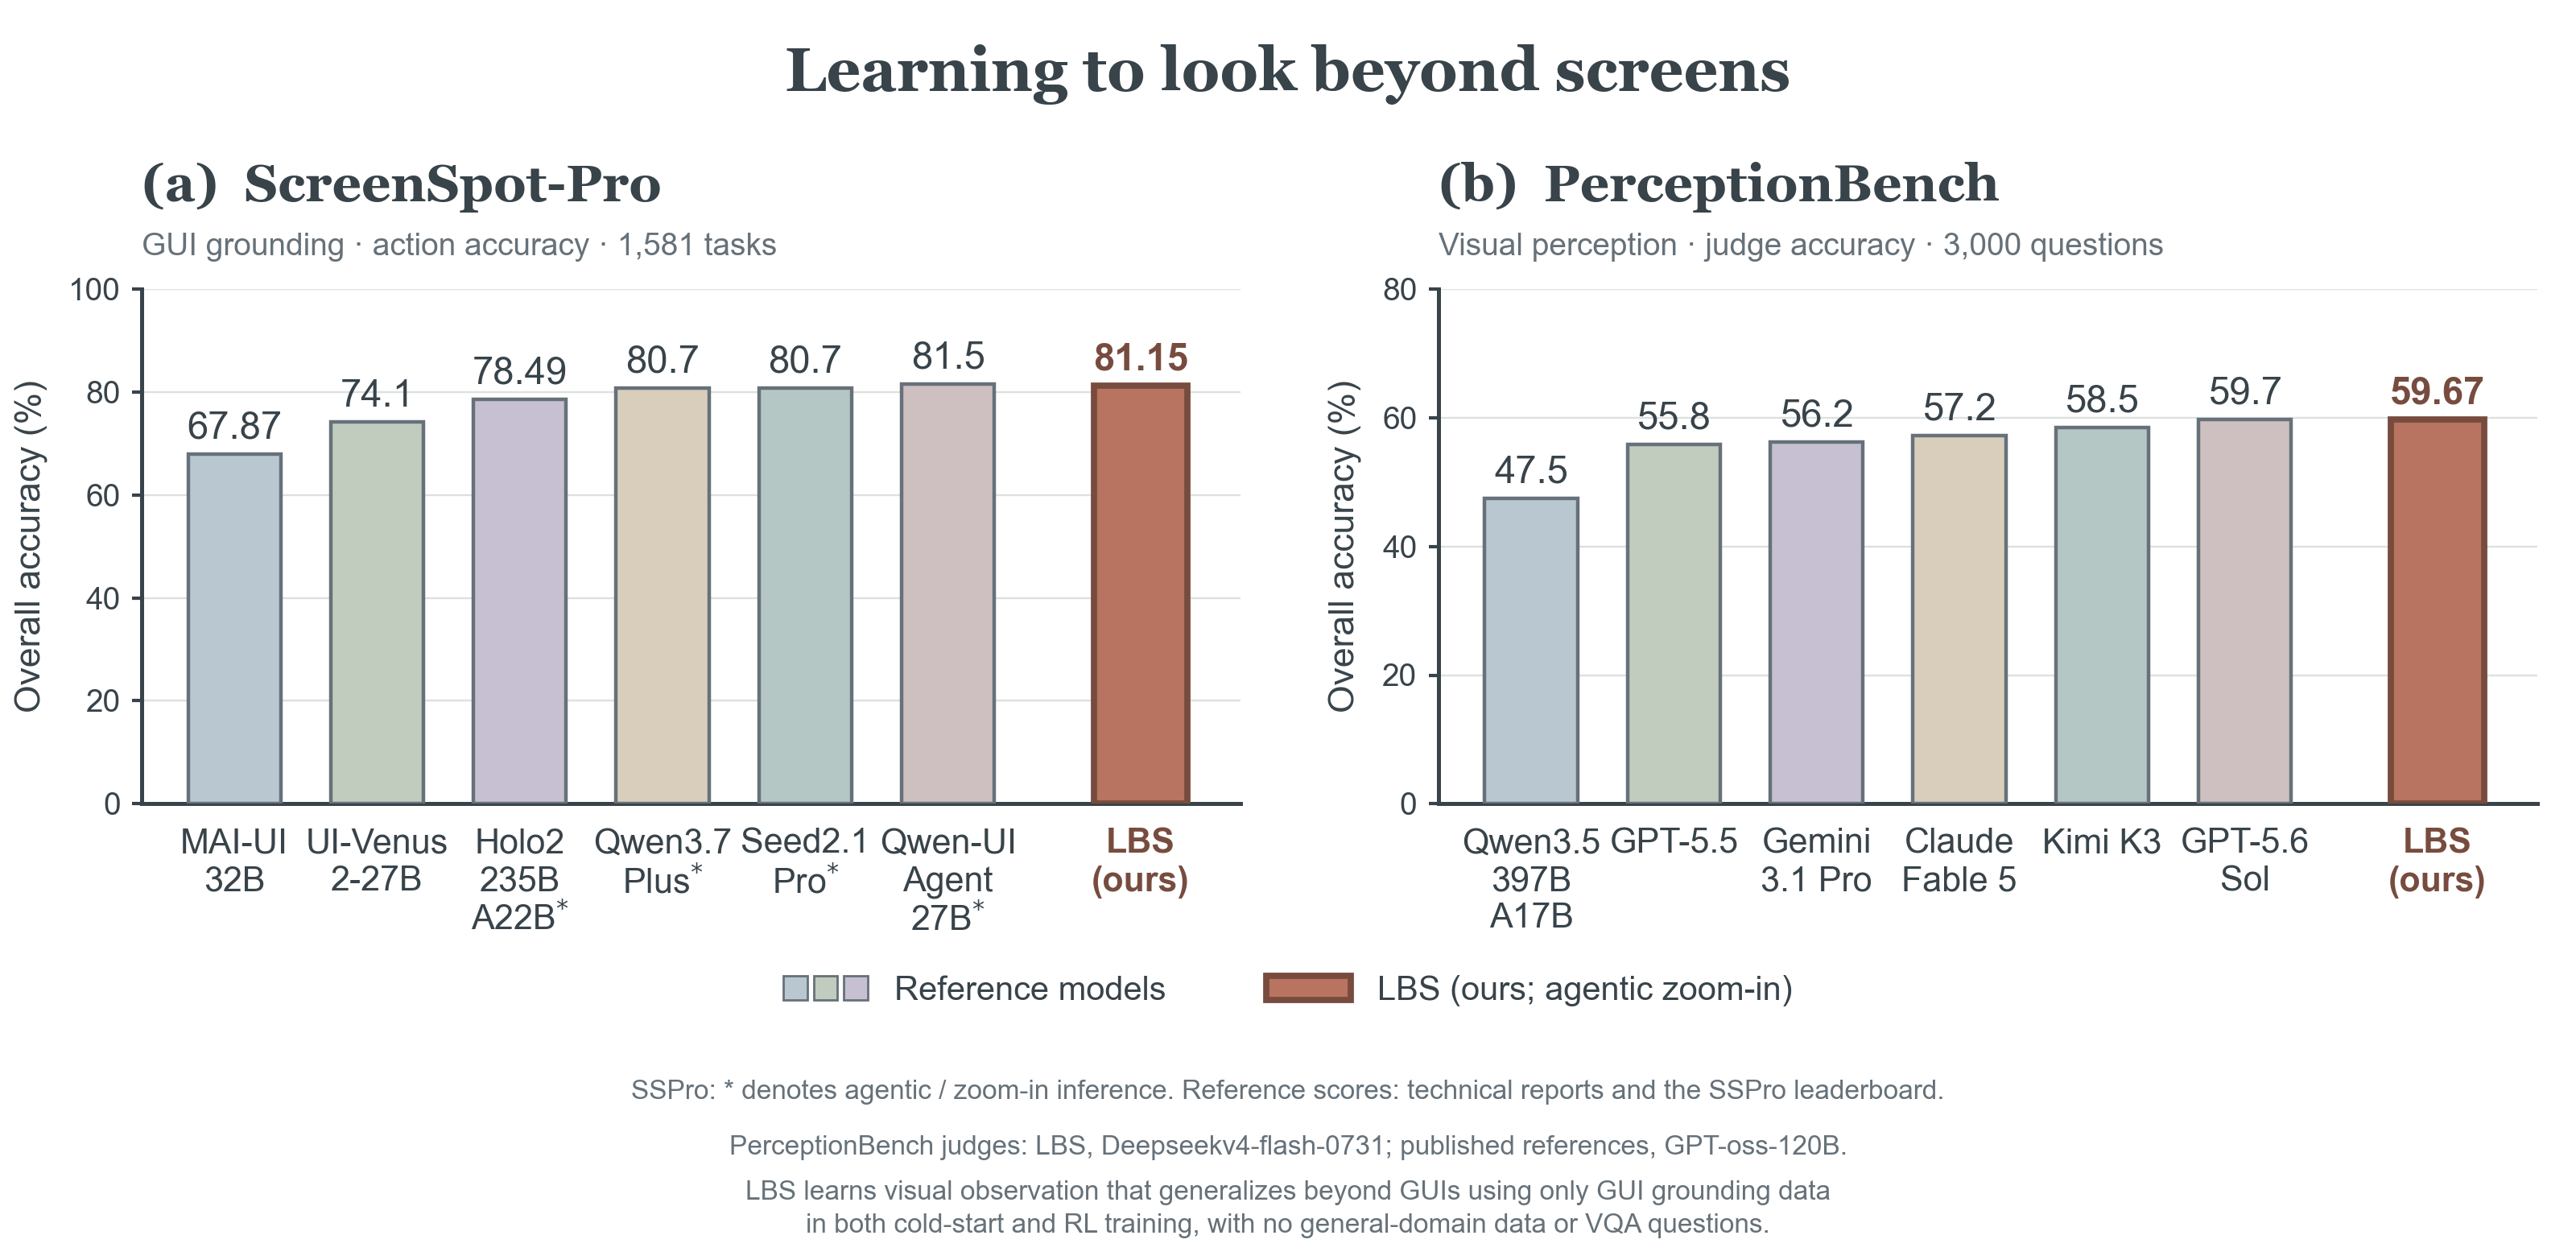
| Benchmark | Records | Metric | Score (%) |
|---|---|---|---|
| ScreenSpot-Pro | 1,581 | Action accuracy | 81.15 |
| OS-World-G (Refine) | 564 | Action accuracy, including refusal | 84.57 |
| PerceptionBench | 3,000 | Judge accuracy | 59.67 |
| HR-Bench 4K | 800 | Strict option matching | 89.13 |
| HR-Bench 8K | 800 | Strict option matching | 87.75 |
All LBS scores use agentic zoom-in over complete benchmark runs. PerceptionBench uses a self-hosted Deepseekv4-flash-0731 judge, with zero failed or skipped judgments; repeated judgments may vary. Chart references use different inference setups and GPT-oss-120B for PerceptionBench, so comparisons are not controlled. See comparison notes.
More result visualizations are available in the LBS project; we have not performed any additional fine-tuning on general-domain data and welcome further RL experiments in specific subdomains.
Serve the released checkpoint in a compatible vLLM environment. Adjust the four-device example below for your hardware:
git clone --branch LBS --single-branch https://github.com/inclusionAI/UI-Venus.git
cd UI-Venus/evaluation
bash scripts/serve_vllm.sh start inclusionAI/LBS-27B \
  --name lbs --tp 4 --dp 1 --daemon
LBS emits plain-text crop_image actions. A client must execute the crops and
return the images and coordinate mappings for multi-turn inference. Final GUI
coordinates use [x.xx,y.yy], normalized to [0,1000] on the original image.
Grounding predicts a location; operating a live application requires a separate
executor.
The evaluation guide
provides the client and benchmark setup. Configure endpoints and credentials in
an ignored .env.run copied from .env.example, using the actual model ID from
/v1/models. Wrappers default to reasoning_effort=xhigh and
thinking_budget=4096 through chat_template_kwargs; direct Python entries can
default to high.
The model weights and project software are released under Apache 2.0. Third-party datasets and screenshots retain their original licenses and terms.